How to improve RAG accuracy? The complete guide to 10 optimization strategies and practical techniques
Many enterprises find, after an initial RAG system build, that real-world answer accuracy falls short of expectations: the AI can't find relevant documents, answers are incomplete, or hallucinations appear. These issues aren't fatal flaws in RAG technology itself — they're the result of insufficient system design and optimization. Improving RAG accuracy is a systematic engineering effort that spans chunking strategy, embedding model selection, hybrid search architecture, re-ranking mechanisms, query optimization, and more, with each improvement delivering a meaningful accuracy gain. Written for engineers and technical leads, this article systematically walks through 10 major RAG optimization strategies, each paired with concrete implementation recommendations, to help you bring your RAG system's performance up to the standard enterprise applications demand.
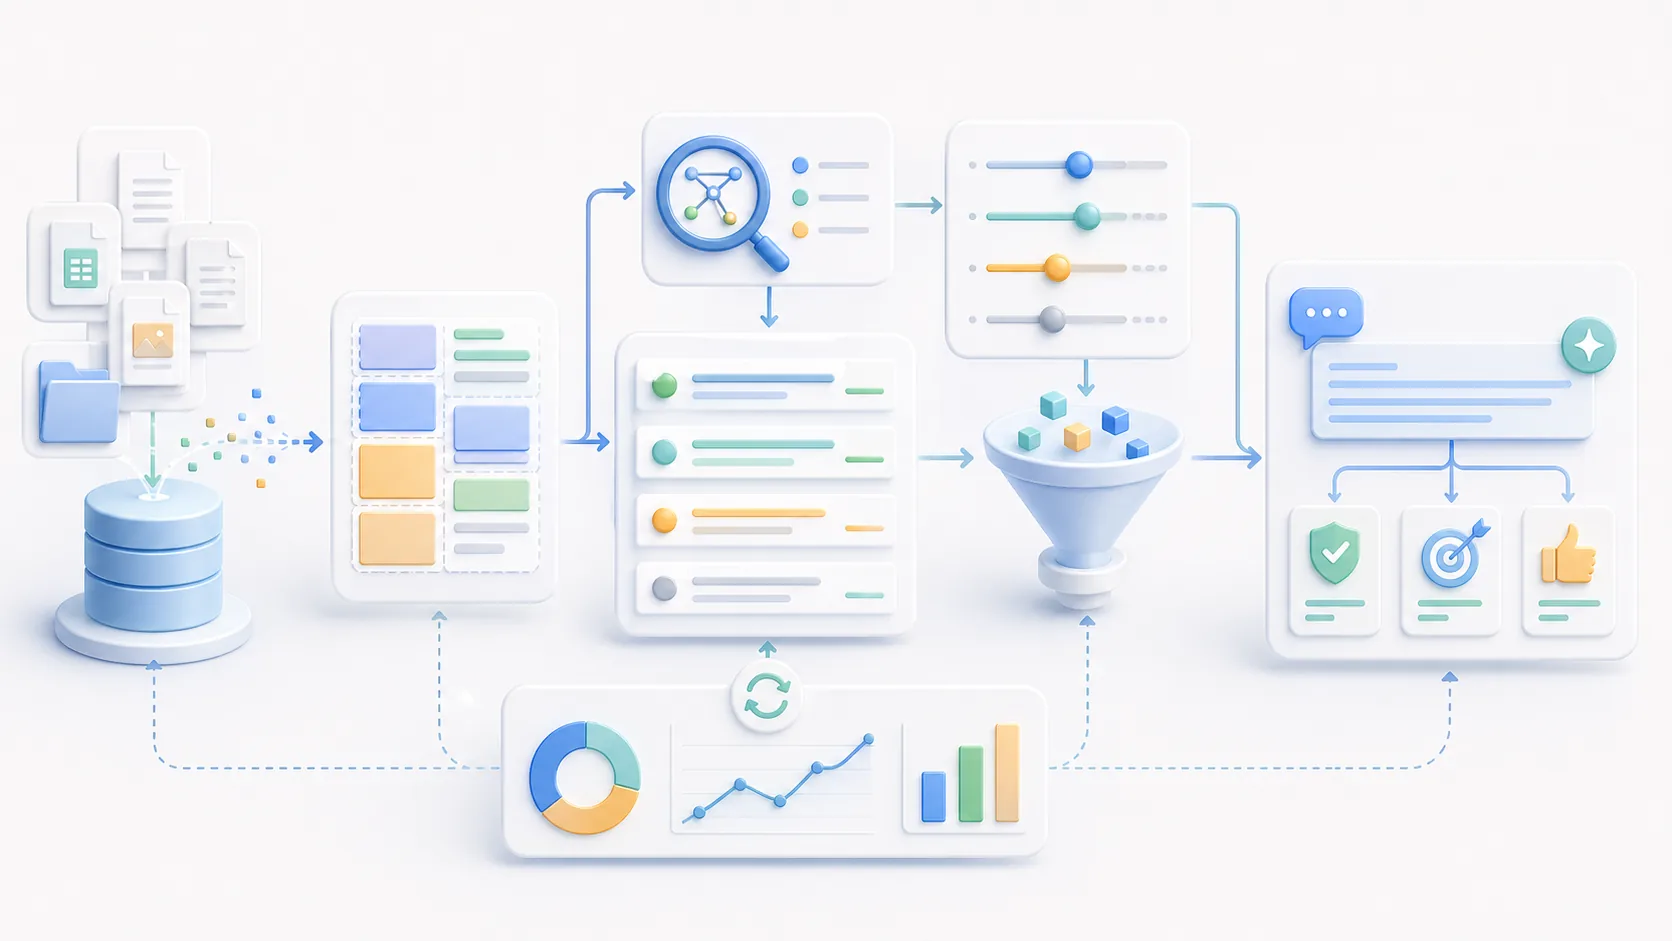
Analysis of the factors affecting RAG accuracy
Before diving into optimization strategies, it helps to understand the core factors that drive RAG accuracy. Overall RAG quality can be measured along three dimensions: "Retrieval Quality" — does the system find document chunks that are genuinely relevant? "Generation Quality" — does the language model correctly make use of the retrieved results? And "Knowledge Base Quality" — is the content in the knowledge base complete, accurate, and well organized? These three dimensions influence one another: optimizing any single dimension improves overall accuracy, but neglecting problems in one dimension will substantially blunt the gains from optimizing the others.
Common RAG accuracy problems fall into a few categories: "Can't find it" (Low Recall) — the relevant document exists in the knowledge base, but the system fails to find it; "Found the wrong thing" (Low Precision) — the system retrieves a large number of documents, but most are irrelevant to the question; "Poor utilization" — relevant documents are retrieved, but the language model fails to extract the correct answer from them; and "Out-of-scope" — the question falls outside the knowledge base's coverage, yet the system still attempts to generate an answer instead of honestly responding "I don't know." Identifying which problem type you're facing is a prerequisite for choosing the right optimization strategy.
Strategies 1-2: Chunking optimization
[Strategy 1] Choose the right chunk size. Chunking is one of the most overlooked yet most impactful steps in a RAG system. If chunks are too large (say, over 1,000 tokens), each fragment carries too much information, so the embedding vector can't precisely capture the topic, blurring similarity calculations. If chunks are too small (say, under 50 tokens), each fragment lacks sufficient context — even when a relevant chunk is retrieved, the language model may fail to generate an accurate answer because the information is incomplete.
Practical recommendation: use different chunk sizes for different document types. For highly structured documents such as regulations or technical specifications, chunk by "clause" or "subsection" (roughly 150-300 tokens); for narrative articles or case studies, chunk by "paragraph" (roughly 300-500 tokens); FAQ documents are typically chunked as one Q&A pair per chunk, regardless of length. Many advanced RAG frameworks support "sliding window" chunking, which keeps a 20-30% overlap between adjacent chunks to make sure context isn't severed across fragments.
[Strategy 2] Adopt semantic chunking. Traditional fixed-size chunking ignores the semantic boundaries of the text and can split a single, complete argument across two chunks. Semantic chunking uses an embedding model to compute the semantic similarity between adjacent sentences and splits at points where similarity drops sharply (signaling a topic shift), ensuring each chunk is semantically self-contained. Frameworks such as LlamaIndex and LangChain both offer semantic chunking implementations, which can substantially improve retrieval quality for knowledge-dense documents.
Strategies 3-4: Embedding model selection and optimization
[Strategy 3] Choose an embedding model suited to your language and domain. The embedding model determines how text is converted into a vector representation, directly affecting the quality of semantic similarity calculations. For Traditional Chinese enterprise documents, general-purpose English embedding models often underperform. We recommend prioritizing multilingual embedding models such as BAAI's BGE-M3 (supports 100+ languages, with strong Traditional Chinese performance), Microsoft's multilingual-e5-large, and Cohere's multilingual-embed-v3. When selecting a model, use the MTEB (Massive Text Embedding Benchmark) leaderboard as a reference, paying particular attention to the Chinese-task sub-rankings.
[Strategy 4] Consider fine-tuning the embedding model. When your knowledge base contains a large volume of domain-specific terminology (such as medicine, law, or semiconductor manufacturing), a general-purpose embedding model may fail to correctly capture the semantic relationships between these terms. Fine-tuning the embedding model on domain data lets the vector space reflect the semantic distances of domain knowledge more precisely. Implementation approach: collect labeled "question — relevant document chunk" pairs and fine-tune the embedding model using contrastive learning. There's no universal number for how much labeled data you'll need — it depends on how many domain terms exist, how hard they are to distinguish from one another, and how familiar the base model already is with the domain. A pragmatic approach is to label a small initial batch (say, a few dozen to one or two hundred pairs), run a trial, and see whether your evaluation-set score starts improving, then decide whether to keep adding data based on diminishing marginal returns. As for how much recall improvement you can expect, that can only be determined by measuring before and after on your own evaluation set — don't cite figures from someone else's project. Two pitfalls worth flagging: first, labeling quality matters more than quantity — if the labeled pairs themselves are wrong or ambiguous, fine-tuning can actually make the vector space worse; second, once an embedding model is swapped or fine-tuned, every vector in the entire knowledge base must be regenerated, and that rebuild cost should be factored into your evaluation.
Strategies 5-6: Hybrid search and re-ranking techniques
[Strategy 5] Implement hybrid search. Pure vector search excels at semantic understanding, but it's less effective than traditional BM25 keyword search at exact keyword matching (such as product model numbers, personal names, or statute numbers). Hybrid search combines both: vector search and keyword search run simultaneously, and the results are merged and re-ranked. A commonly used fusion method is RRF (Reciprocal Rank Fusion), which sums the reciprocal ranks of each document across the two result lists to produce a final hybrid ranking. Hybrid search tends to help for a concrete reason: vector search may treat "model A123-B" and "model A123-C" as nearly identical in meaning and confuse them, whereas keyword search hits precisely; conversely, keyword search is powerless against synonymous rewording, which is where vector search comes in. As a result, the denser a knowledge base is with proper nouns, model numbers, and statute references, the more pronounced the benefit of hybrid search tends to be. The actual improvement should be measured against your own evaluation set, and note that RRF's weighting needs tuning: weighting too far toward keywords sacrifices semantic queries, while weighting too far toward vectors loses the benefit of exact matching. Mainstream solutions such as Elasticsearch, Weaviate, and Qdrant already support hybrid retrieval.
[Strategy 6] Add a re-ranking layer. The initial results from vector search (typically the top 20 to top 50) are reasonable in terms of semantic similarity, but they aren't necessarily the chunks most helpful for "answering this specific question." A re-ranking model (cross-encoder) takes "question + document chunk" as input and directly computes a score for "how much this chunk helps answer this question," which is more precise than the vector similarity produced by a two-tower (bi-encoder) architecture. Recommended re-ranking models include the Cohere Rerank API, BGE-Reranker, and Jina Reranker. A typical pipeline: retrieve the top 20 via vector search, then use a re-ranker to narrow it down to the top 5 before passing them to the language model — this substantially reduces the amount of irrelevant context fed into the LLM.
Strategies 7-8: Query optimization and context management
[Strategy 7] Query rewriting and HyDE. A user's original question is often not the ideal form for vector search: it may be vague, overly conversational, or use terminology that differs from what's in the knowledge base documents. Query rewriting uses an LLM to rephrase the user's question into a more search-friendly form before retrieval — expanding abbreviations, filling in implicit context, or generating multiple search queries from different angles (multi-query retrieval). Another powerful technique is HyDE (Hypothetical Document Embeddings): the LLM first "hypothesizes" a document chunk that might answer the question, then uses that hypothetical document's embedding vector to perform the search — this is usually more effective than searching directly with the question's own vector.
[Strategy 8] Context compression and curation. When the context passed to an LLM is too long, the model often struggles to accurately pick out the most critical information, leading to the "lost in the middle" phenomenon — information in the middle sections is far more likely to be ignored than information at the beginning or end. The goal of context compression is to trim each retrieved chunk before passing it to the LLM: keep the sentences directly relevant to the question and filter out irrelevant background information. LangChain's ContextualCompressionRetriever provides an out-of-the-box implementation. Research also shows that placing the most important document chunks at the beginning of the context (rather than in the middle) can significantly improve how effectively the LLM makes use of them.
Strategies 9-10: Evaluation methods and continuous monitoring
[Strategy 9] Use a framework such as RAGAS for systematic evaluation. Many enterprise RAG systems lack an objective evaluation mechanism and judge whether things have improved purely by "feel." RAGAS (Retrieval-Augmented Generation Assessment) is one common option among RAG evaluation frameworks — different teams actually use different evaluation tools in practice, and quite a few enterprises build their own evaluation scripts. RAGAS's four core metrics are well worth referencing: Faithfulness (is the answer grounded in the evidence?), Answer Relevancy (does the answer actually address the question?), Context Precision (what proportion of the retrieved results are genuinely relevant?), and Context Recall (was all the relevant information found?). Combining these four metrics lets you diagnose whether a RAG system's bottleneck lies in retrieval, ranking, or generation. There's one limitation worth noting when using automated evaluation tools like this: most of these metrics are themselves computed with an LLM acting as judge, so scores are influenced by the judge model's version and prompt design — absolute scores from different times or different judge models shouldn't be directly compared. A pragmatic approach is to fix the judge model and prompt, treat the score as a "relative trend under the same conditions" for tracking whether optimizations are working, and periodically spot-check a small batch of cases manually to confirm the automated scores haven't drifted from human judgment.
| RAGAS metric | What it measures | Optimization strategy when the score is low |
|---|---|---|
| Faithfulness | Whether the answer is generated based on the retrieved documents, without fabrication | Improve prompt design, emphasizing "answer only based on the provided information" |
| Answer Relevancy | Whether the answer actually addresses the question | Improve query rewriting and how context is organized |
| Context Precision | How much of the retrieved content is genuinely useful | Add re-ranking, improve the embedding model |
| Context Recall | Whether all relevant information was found | Use hybrid search, increase the Top-K count, improve chunking |
[Strategy 10] Establish continuous monitoring and an online feedback mechanism. Optimizing a RAG system isn't a one-time job — it's an ongoing, iterative process. We recommend setting up the following monitoring: log the question text, retrieval results, generated answer, and user feedback (such as thumbs up/down) for every query; periodically analyze queries that "couldn't be answered" or received "poor-quality answers" to identify gaps in knowledge base coverage; monitor system metrics such as retrieval latency and API cost; and periodically (e.g., quarterly) re-run a standard set of test questions to track long-term trends in system quality. The real value of this monitoring setup is turning optimization from guesswork into verifiable iteration: every adjustment has a before-and-after score comparison, failure cases accumulate into new evaluation questions, and gaps in knowledge base coverage get proactively surfaced. As for how much improvement to expect and how long it will take, that depends on your starting baseline, data quality, and the number of iterations invested — there's no universal figure to promise. We recommend validating by milestone instead: set a target metric and a minimum improvement threshold for each iteration round, and treat "two consecutive rounds with no significant improvement on the same evaluation set" as the signal that the current architecture has converged — at which point it's worth considering a model swap or an architecture change.
Further Reading
- What Is RAG? The Principles, Architecture, and Enterprise Applications of Retrieval-Augmented Generation
- RAG vs. fine-tuning: a complete comparison guide to the key choice in enterprise AI deployment
- Enterprise RAG use cases explained: adoption priorities and benefit measurement for finance, government, and manufacturing
FAQ
References
- Es, S., et al. (2023). RAGAS: Automated evaluation of retrieval augmented generation. [arXiv:2309.15217]
- Ma, X., et al. (2023). Fine-tuning LLaMA for multi-stage text retrieval. SIGIR 2024. [arXiv]
- Gao, L., et al. (2022). Precise zero-shot dense retrieval without relevance labels (HyDE). [arXiv:2212.10496]
- Liu, N., et al. (2023). Lost in the middle: How language models use long contexts. TACL 2024. [arXiv]
Want to improve your RAG system's accuracy faster?
Contact LargitData's technical consultants — we offer a RAG system health diagnostic service to help you quickly identify bottlenecks and build an optimization roadmap.
Contact Us